Prompt edits without evaluation are deployments without tests. Serious LLM apps need golden sets, graders, and CI checks that catch silent quality drops.
Treat prompts like code
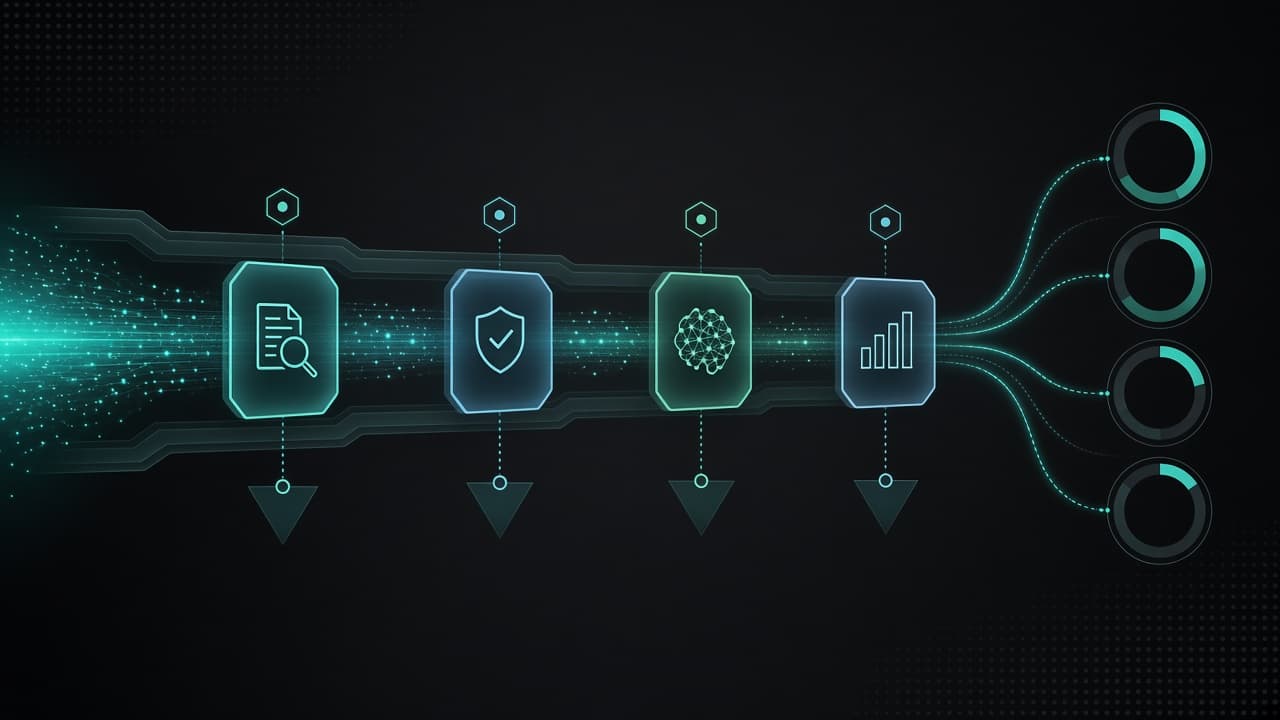
Version them. Review them. Run them through automated checks before production. A clever prompt that breaks three old cases is a regression, not an improvement.
Build an evaluation spine
Start with a curated set of real user tasks, expected behaviors, and known failure cases. Combine automatic graders with periodic human review for nuance.
Wire evaluations into CI so model or prompt changes cannot ship blind. This is the heart of modern LLMOps and AI quality engineering.
Optimize for learning speed
The goal is not a perfect score once. It is a pipeline that tells you quickly when quality moved — and why — so the team can respond with evidence.